RAG and LLM Evaluation Components for React
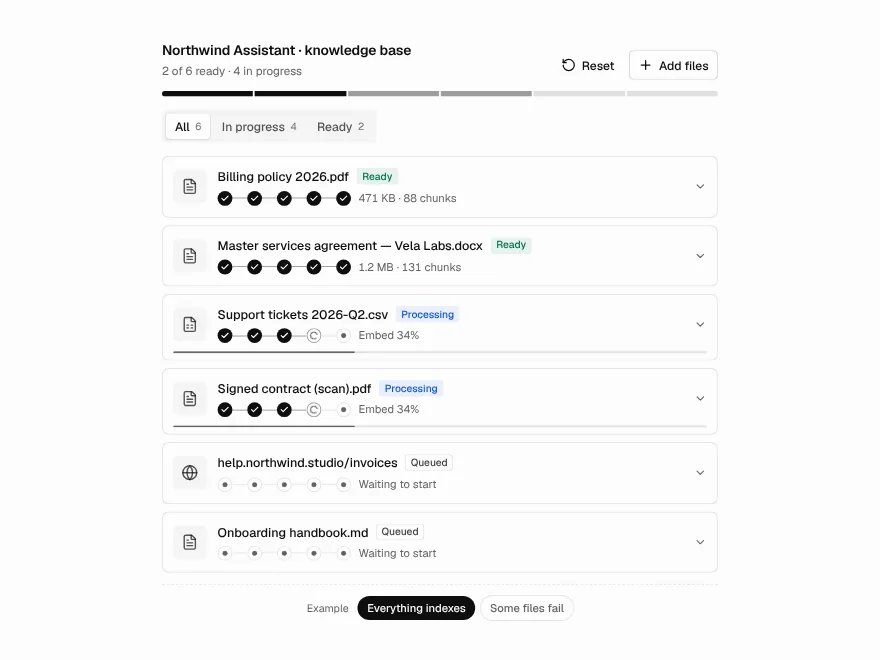
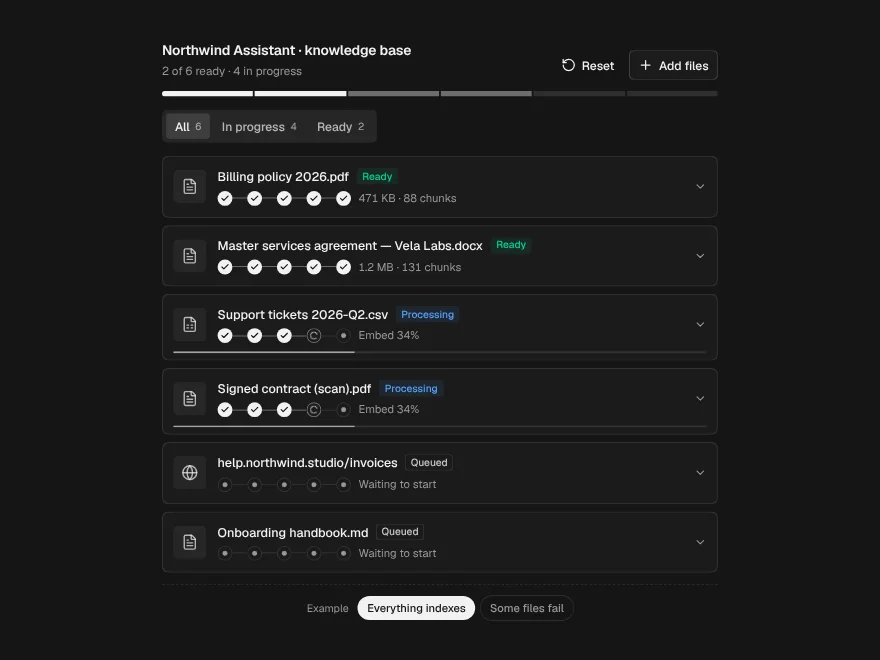
The screens you build once an AI feature is real and has to be trusted: what the retriever found and what reached the model, whether each claim in an answer is backed by its source, where a document got stuck on its way into the index, and how much of the context window each part took.
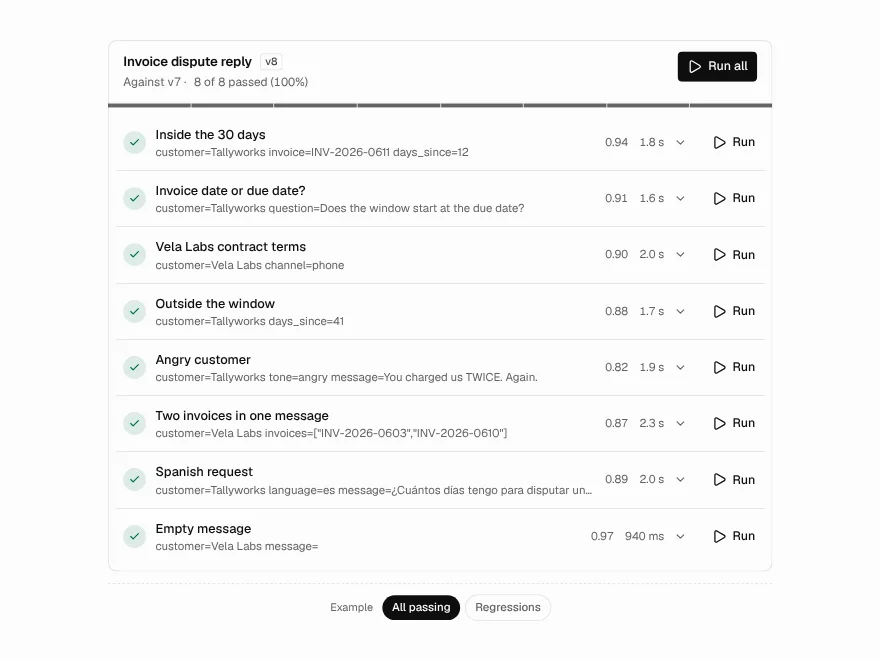
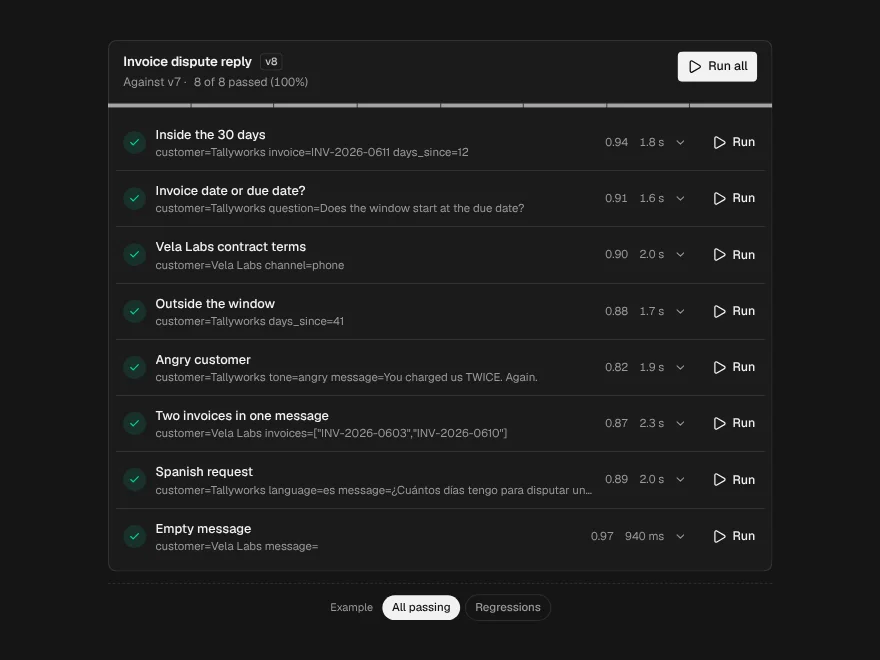
For the work of improving a prompt or choosing a model, a test matrix shows every case with expected and actual output and calls out regressions, and a comparison view puts several models' answers side by side with time, tokens and cost. Each component renders the data you pass and reports what the user does; none of them calls a model or a database.
10 components, 1 free. React, TypeScript and Tailwind CSS, light and dark.
All AI UI components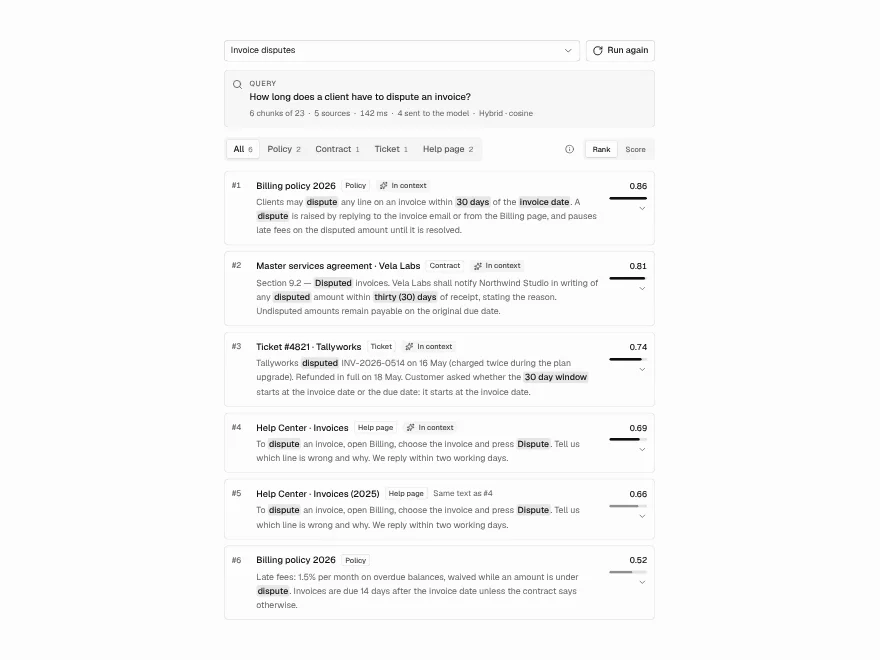
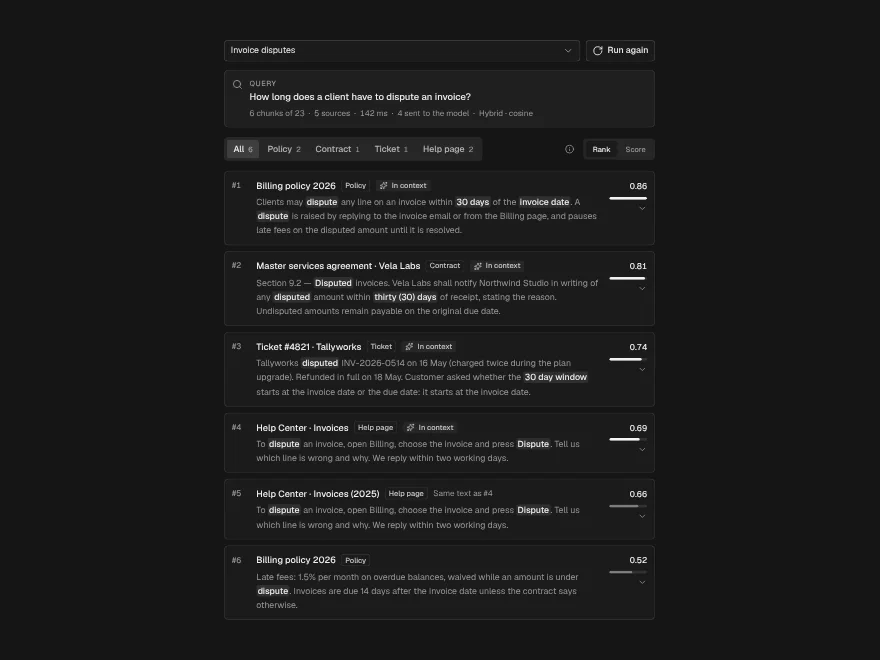
Retrieval Inspector
PaidWhat the retriever found for a question, and which chunks reached the model.
Included with lifetime access
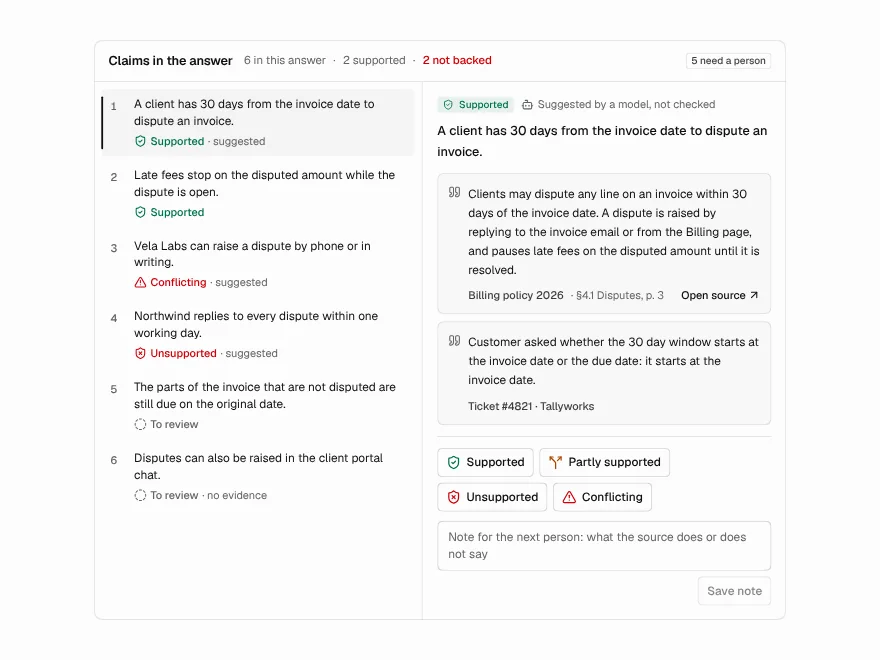
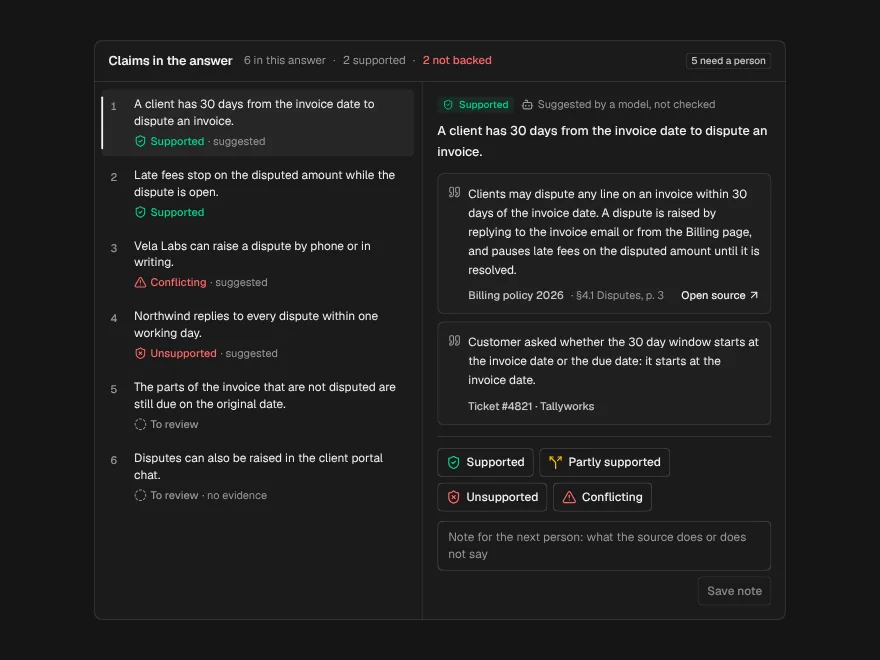
Citation Verification
PaidEach claim in an answer beside the evidence, with a verdict a person can set.
Included with lifetime access
Ingestion Pipeline
PaidFiles going into a knowledge base, each with its own chain of steps.
Included with lifetime access
Prompt Test Matrix
PaidA prompt against its test cases: expected, actual, and what regressed.
Included with lifetime access
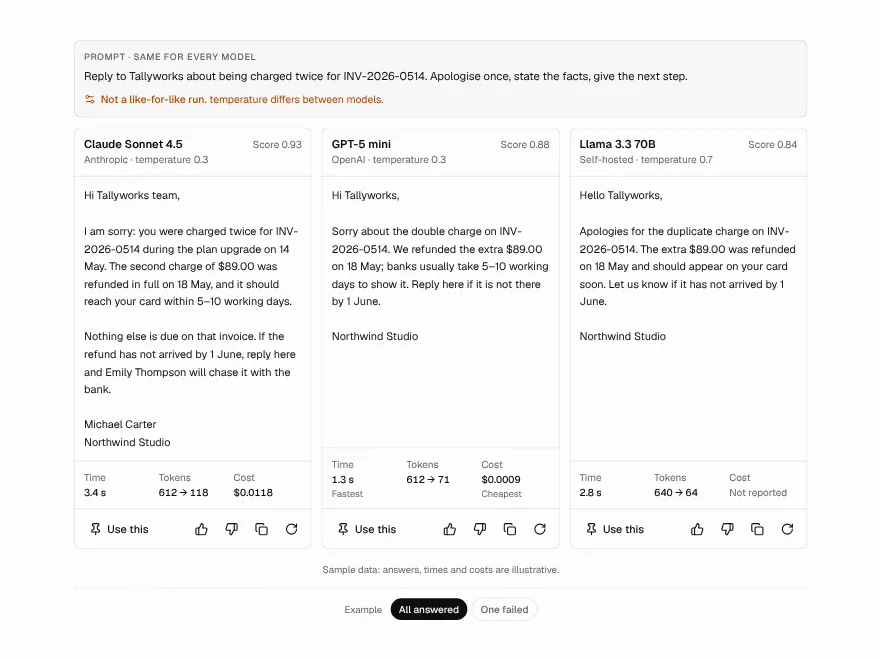
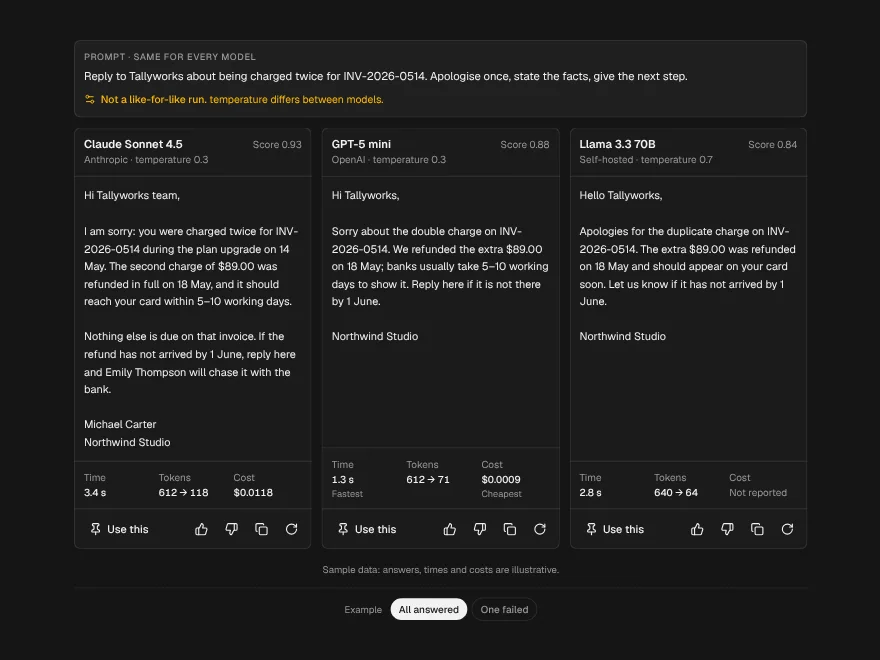
Model Comparison
PaidOne prompt, several models, answers side by side with time, tokens and cost.
Included with lifetime access
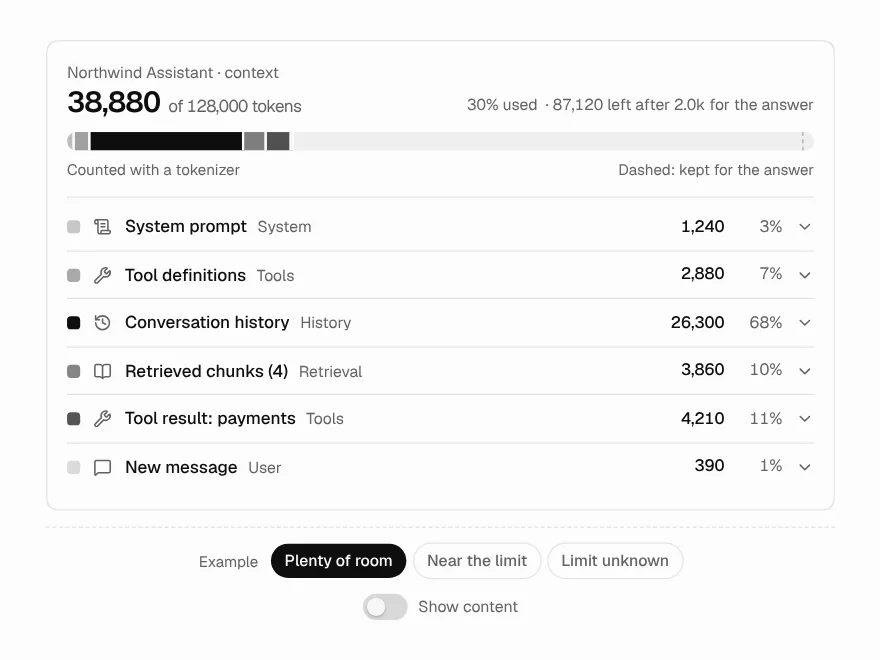
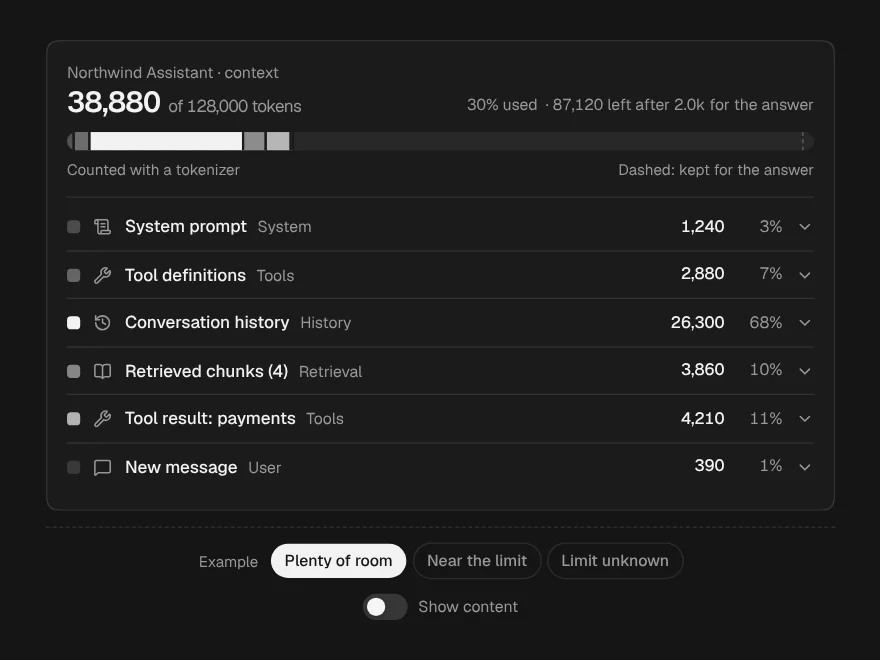
Context Window
FreeWhat filled a model's context, part by part, and what was cut.
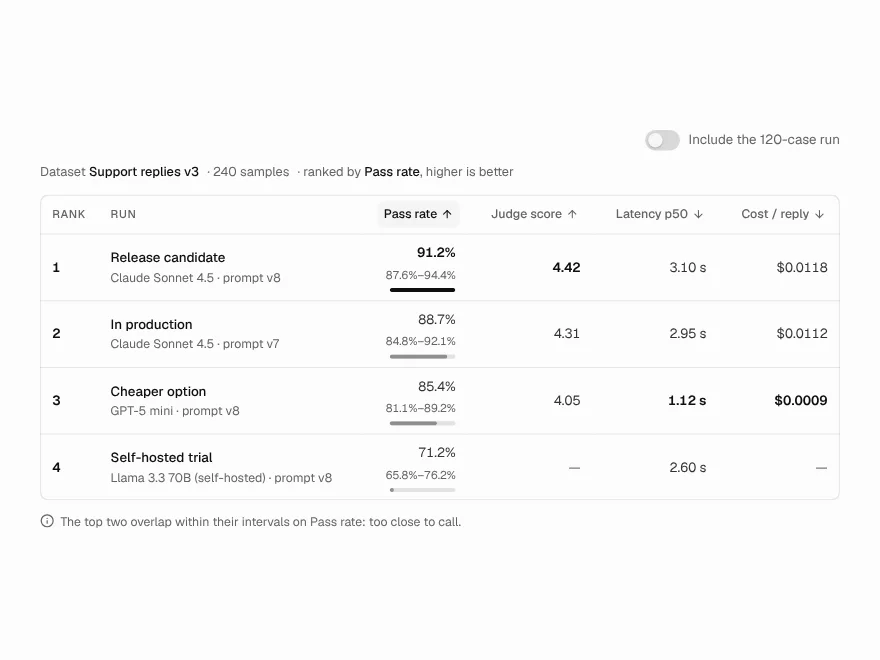
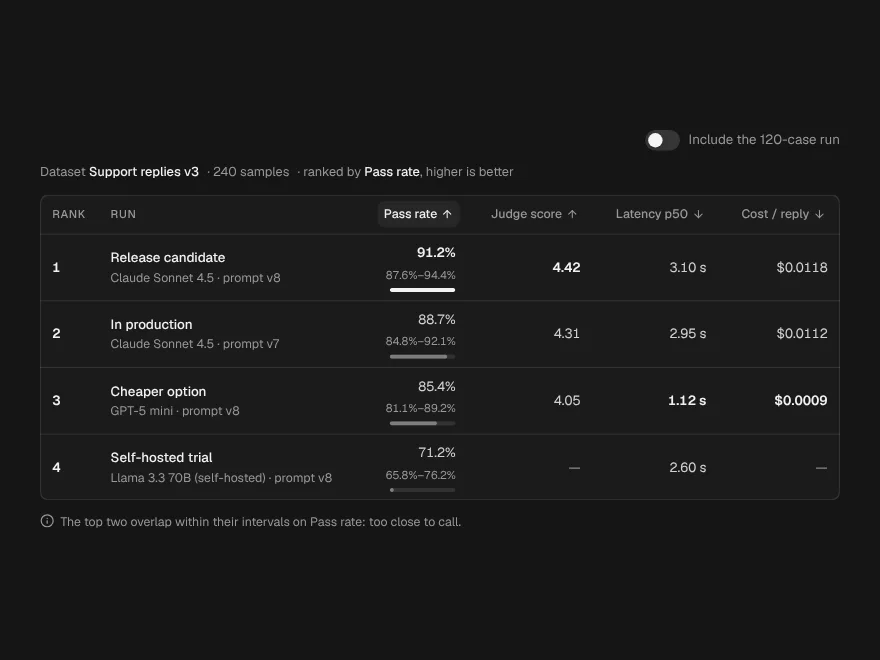
Eval Leaderboard
PaidModels and prompts ranked on one evaluation, with the caveats on screen.
Included with lifetime access
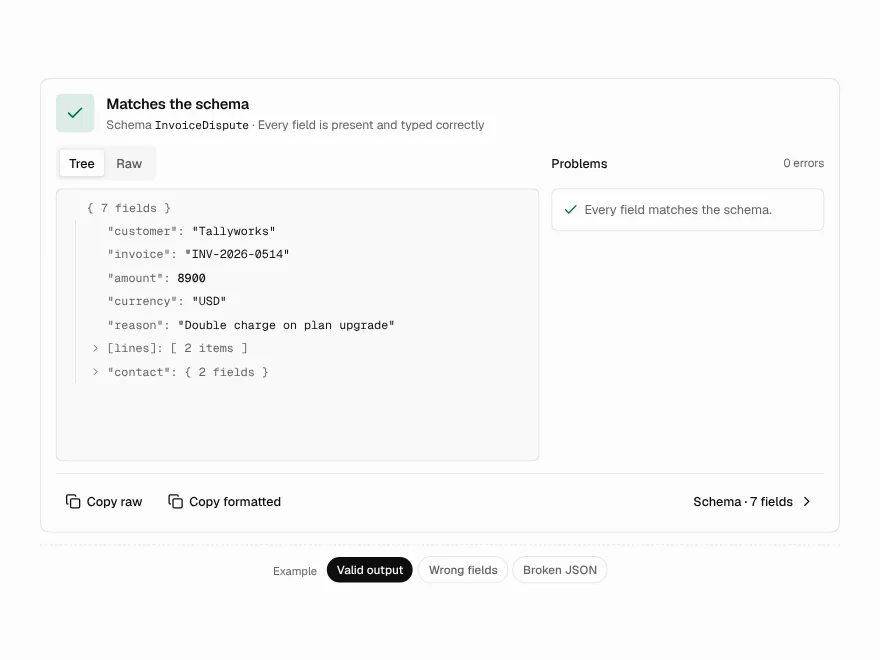
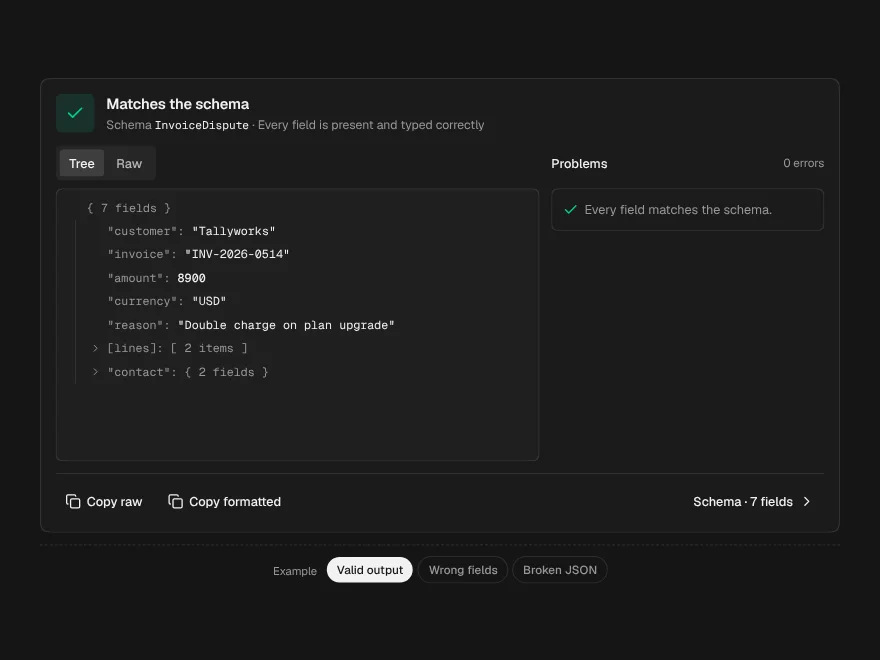
Output Validator
PaidA model's JSON checked against its schema, with each problem on its field.
Included with lifetime access
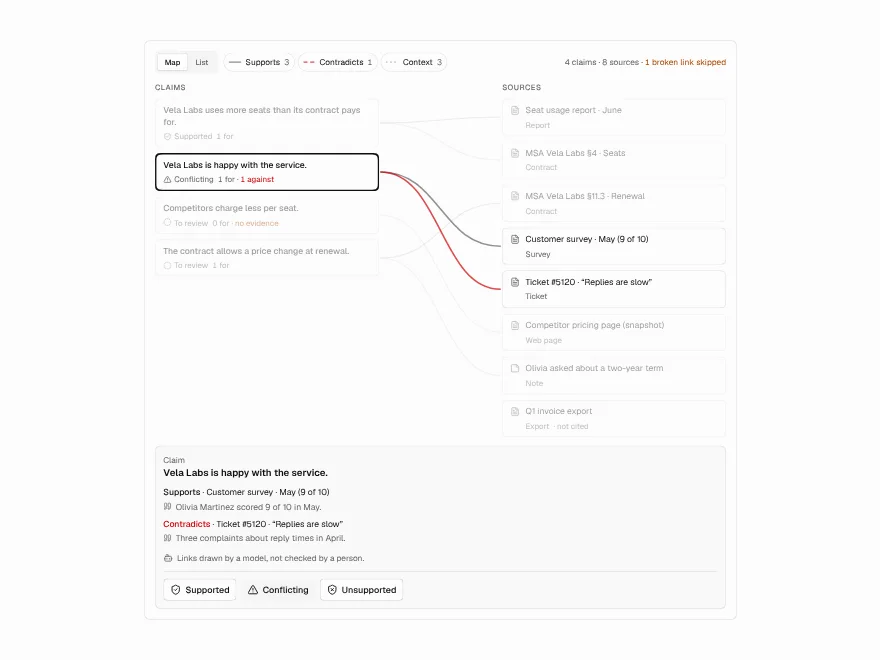
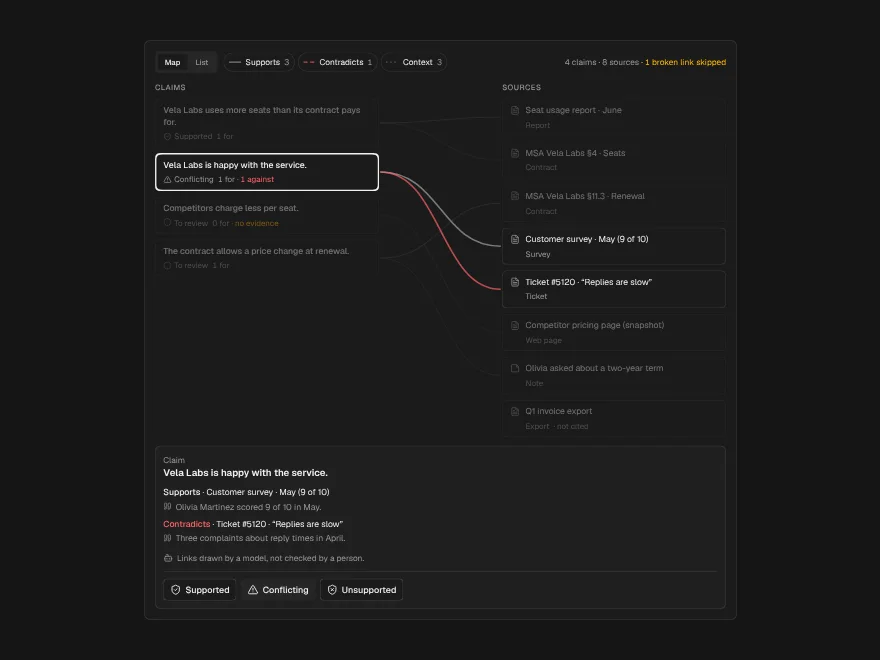
Evidence Map
PaidClaims and sources joined by what supports, contradicts or only gives context.
Included with lifetime access
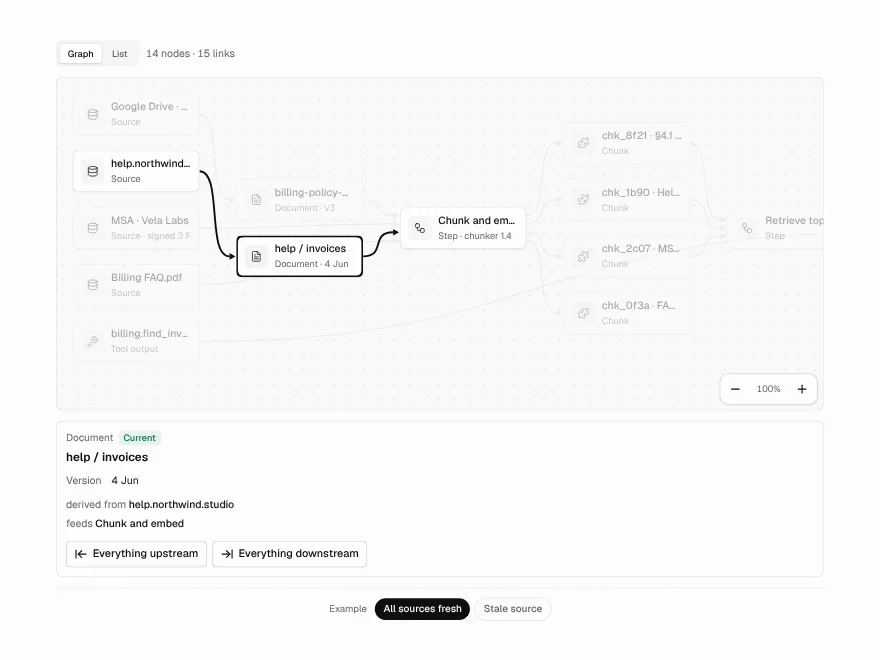
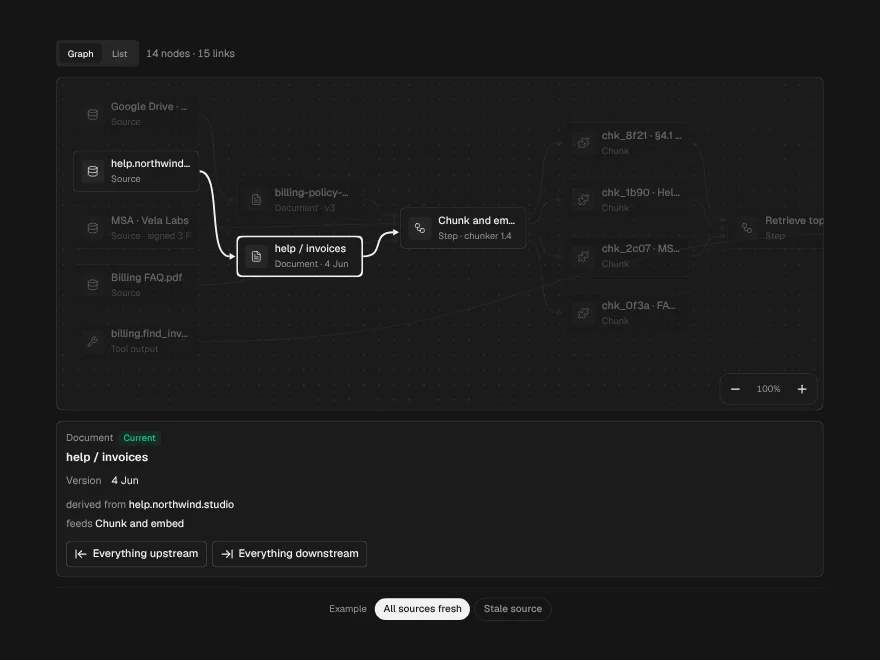
Data Lineage
PaidWhere an AI output came from, and which upstream data is stale or missing.
Included with lifetime access